How Far Can We Go With ImageNet for Text-to-Image Generation?
1LIX, École Polytechnique ·
2AMIAD ·
3Kyutai ·
4LIGM, École des Ponts
*Equal contribution †Equal supervision
TL;DR
Is "bigger is better" the only way?
Text-to-image models are usually trained on billion-scale web datasets, which are either closed or decaying over time. We show that a model trained on ImageNet alone (1.2M images), enhanced with well-designed text and image augmentations, reaches the GenEval score of FLUX-dev and outperforms SD3 and SDXL, with 1/1000th of the training images and 3× to 10× fewer parameters. The standardized training setup only needs about 500 H100 hours, which makes text-to-image research reproducible and accessible.
GenEval
DPGBench
Overall score vs. training set size (log scale). Bubble area is proportional to the number of parameters. Models whose training data is undisclosed are shown on the right.
1 · Text challenges
ImageNet has no captions
ImageNet is a classification dataset. The simplest caption, "An image of ⟨class name⟩" (AIO), gives very poor text-to-image models: it has only about a thousand words, ignores everything in the image besides the class, and has no word for concepts such as person, road or water, which appear in many images but are not classes.
Long informative captions (TA). We re-caption every image with LLaVA, describing scene composition, background, secondary objects, attributes and actions. The same captioner describes our CutMix images (see below). Pick an image:
AIO An image of ⟨class name⟩
TA
Long captions transform ImageNet into a text-to-image dataset. On ImageNet validation, FID drops from 20.14 to 6.29 for DiT-I; on COCO, which is zero-shot for our models, only TA models follow the prompt (Jina CLIP 22.42 → 38.39). GenEval jumps from 0.11 to 0.55.
| Model | Caption | FID IN-Val ↓ | FID COCO ↓ | Jina CLIP COCO ↑ | GenEval ↑ |
|---|---|---|---|---|---|
| DiT-I | AIO | 20.14 | 71.00 | 22.42 | 0.11 |
| TA | 6.29 | 45.71 | 38.39 | 0.55 | |
| TextRIN-I | AIO | 84.77 | 46.35 | 14.06 | 0.17 |
| TA | 6.16 | 49.89 | 37.85 | 0.55 |
2 · Image challenges
Overfitting and object-centric images
Even with long captions, ImageNet-only training faces two limitations. Early overfitting: with only 1.2M images, latent-space models start to overfit after about 200k steps. Limited compositionality: ImageNet is object-centric, so models struggle with spatial relations, attribute binding and multi-object scenes.
Image augmentation (IA). We study two augmentations:
- CutMix: a smaller image from another class is pasted onto the original image, and the composite is re-captioned. To avoid learning the sharp paste boundaries, CutMix images are only used at noise levels where the boundary is no longer visible.
- Crop: the model only sees a random local crop of the image tokens, with the crop coordinates added to the caption. This helps decouple objects from their background.
TextRIN-I
SiT-I
JiT-I
GenEval score during training. Image augmentation delays or prevents overfitting for the latent-space models (TextRIN-I, SiT-I). The pixel-space JiT-I does not overfit and does not benefit from it.
Image augmentation helps the latent-space models, and SiT-I benefits the most: with CutMix, its GenEval jumps by +10 points (to 0.61), driven by color attribution (+16) and two objects (+13), and ImageReward goes from −0.12 to 0.22. In contrast, the pixel-space JiT-I degrades slightly. We attribute this to the VAE of latent models, whose encoder absorbs the sharp, locally unnatural CutMix boundaries; JiT-I models raw pixels and has no such filter.
| Model | IA | GenEval ↑ | Two obj. ↑ | Position ↑ | Col. attr. ↑ | ImageReward ↑ |
|---|---|---|---|---|---|---|
| DiT-I | – | 0.55 | 0.61 | 0.28 | 0.33 | 0.18 |
| Crop | 0.54 | 0.56 | 0.22 | 0.33 | 0.12 | |
| CutMix | 0.58 | 0.67 | 0.30 | 0.35 | 0.26 | |
| TextRIN-I | – | 0.55 | 0.60 | 0.26 | 0.35 | 0.22 |
| Crop | 0.54 | 0.61 | 0.23 | 0.33 | −0.10 | |
| CutMix | 0.57 | 0.68 | 0.35 | 0.36 | 0.30 | |
| SiT-I | – | 0.51 | 0.56 | 0.25 | 0.24 | −0.12 |
| Crop | 0.59 | 0.66 | 0.28 | 0.39 | 0.07 | |
| CutMix | 0.61 | 0.69 | 0.34 | 0.40 | 0.22 | |
| JiT-I | – | 0.54 | 0.62 | 0.24 | 0.29 | −0.01 |
| Crop | 0.51 | 0.53 | 0.20 | 0.26 | −0.09 | |
| CutMix | 0.50 | 0.57 | 0.22 | 0.27 | −0.07 |
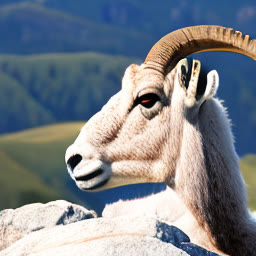
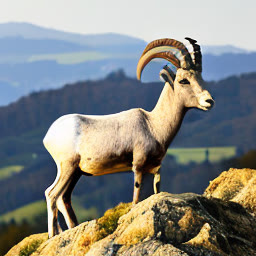
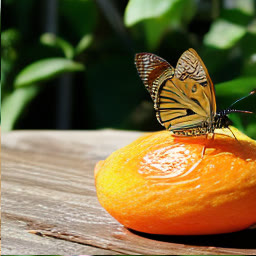
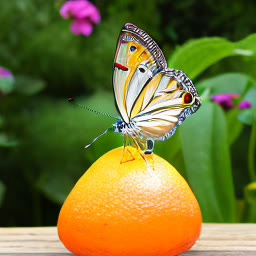
Image augmentation also improves compositions. With TA only, the teddy bear sits awkwardly on the motorbike; with TA + IA it drives it. The goat scene is better composed, and color attribution improves for the butterfly and the baseballs.
 TA
 TA + IA
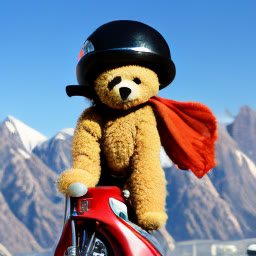 TA
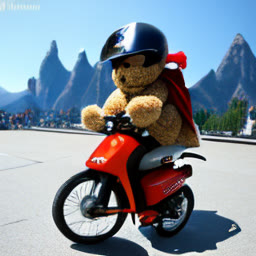 TA + IA
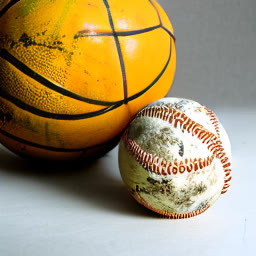 TA
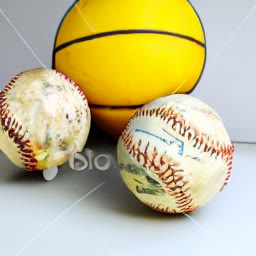 TA + IA
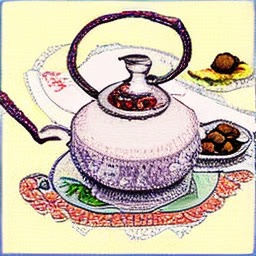 TA
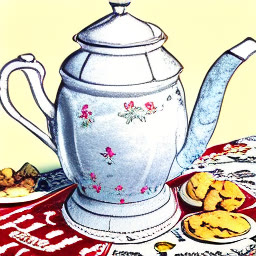 TA + IA
 TA
 TA + IA
 TA
 TA + IA
3 · Conditioning with MIRO
Learning preferences during pretraining
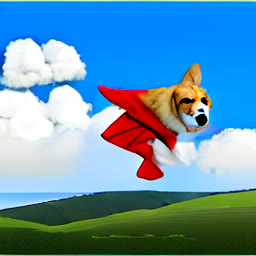
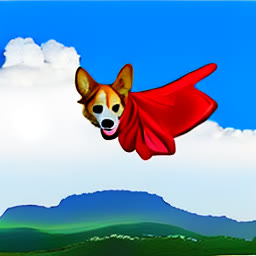
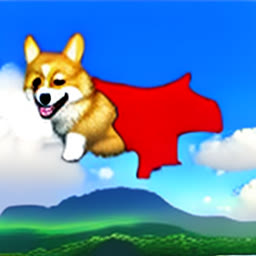
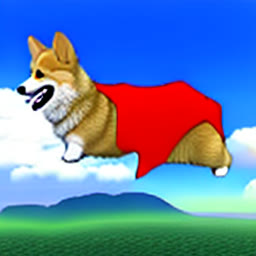
MIRO conditions text-to-image pretraining on multiple reward signals, so the model learns user preferences directly instead of relying on post-hoc reward fine-tuning. In our ImageNet-only setting, MIRO improves SiT-I by +5 GenEval points (0.51 → 0.56) and ImageReward from −0.12 to 0.29. The gain is smaller than in the original paper with web-scale data, and smaller than what CutMix alone brings.
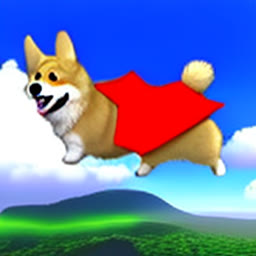
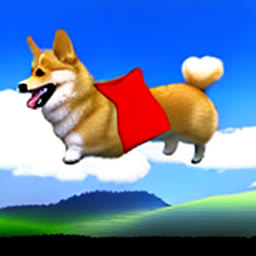
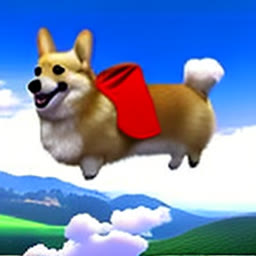 + MIRO
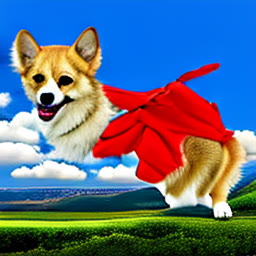
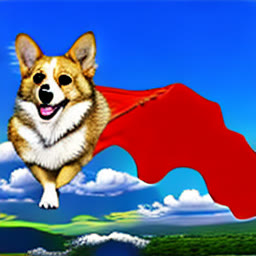
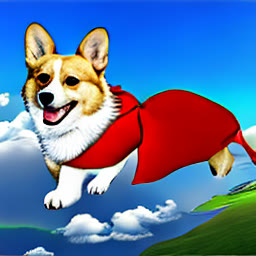
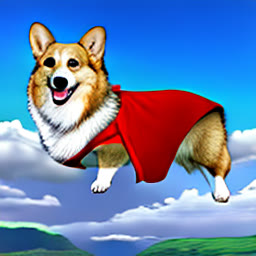
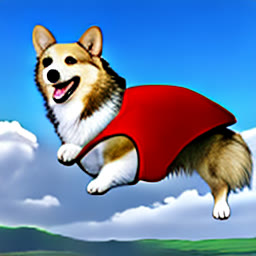
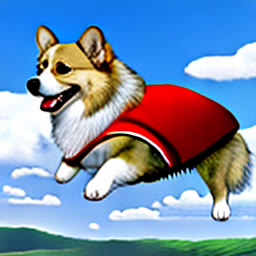
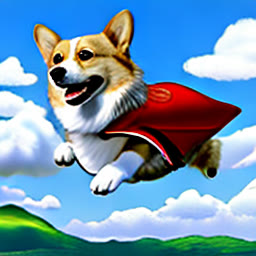
“a fluffy corgi dog mid-flight with a red superhero cape”
4 · Scaling
Bigger models and higher resolution
Model size. Scaling SiT-I CutMix from L to XL and H does not improve compositionality: GenEval stays flat, suggesting that the L model already extracts most of what ImageNet offers for this benchmark. Aesthetic metrics improve slightly with size. Resolution. Going to 512², either by fine-tuning a 256² checkpoint (DiT-I) or training from scratch (SiT-I), improves both GenEval and aesthetics.
Model size (SiT-I CutMix, 256²)
| Size | GenEval ↑ | Aes. Score ↑ | ImageReward ↑ |
|---|---|---|---|
| L | 0.61 | 5.33 | 0.22 |
| XL | 0.58 | 5.33 | 0.23 |
| H | 0.61 | 5.37 | 0.30 |
Resolution
| Model | Res. | GenEval ↑ | ImageReward ↑ |
|---|---|---|---|
| DiT-I (fine-tuned) | 256² | 0.58 | 0.26 |
| 512² | 0.61 | 0.40 | |
| SiT-I (from scratch) | 256² | 0.61 | 0.22 |
| 512² | 0.63 | 0.37 |
Putting everything together
We combine the best ingredients into a single model: SiT-H trained with CutMix and MIRO conditioning. At 512², it reaches 0.67 on GenEval and an ImageReward of 0.73.
| Model | Res. | GenEval ↑ | Two obj. ↑ | Col. attr. ↑ | PickScore ↑ | HPSv2.1 ↑ | ImageReward ↑ |
|---|---|---|---|---|---|---|---|
| SiT-H CutMix + MIRO | 256² | 0.65 | 0.73 | 0.49 | 20.59 | 0.27 | 0.67 |
| 512² | 0.67 | 0.82 | 0.52 | 20.84 | 0.28 | 0.73 |
5 · Comparison with the state of the art
GenEval
Our best model reaches 0.67 overall, matching FLUX-dev and surpassing SANA-0.6 (0.64) and SD3 Medium (0.62), all trained on orders of magnitude more data. It obtains the best Two Objects score (0.82), but falls behind on Counting.
| Model | Size | #data | Overall ↑ | One obj. | Two obj. | Count. | Col. | Pos. | Col. attr. |
|---|---|---|---|---|---|---|---|---|---|
| SD v1.5 | 0.9B | 5B+ | 0.43 | 0.97 | 0.38 | 0.35 | 0.76 | 0.04 | 0.06 |
| PixArt-α | 0.6B | 25M | 0.48 | 0.98 | 0.50 | 0.44 | 0.80 | 0.08 | 0.07 |
| PixArt-Σ (512) | 0.6B | 35M+ | 0.52 | 0.98 | 0.59 | 0.50 | 0.80 | 0.10 | 0.15 |
| SD v2.1 | 0.9B | 5B+ | 0.50 | 0.98 | 0.51 | 0.44 | 0.85 | 0.07 | 0.17 |
| SDXL | 3.5B | 5B+ | 0.55 | 0.98 | 0.74 | 0.39 | 0.85 | 0.15 | 0.23 |
| SD3 M (512) | 2B | 1B+ | 0.62 | 0.98 | 0.74 | 0.63 | 0.67 | 0.34 | 0.36 |
| SANA-0.6 | 0.6B | undiscl. | 0.64 | 0.99 | 0.71 | 0.63 | 0.91 | 0.16 | 0.42 |
| FLUX-dev | 12B | undiscl. | 0.67 | 0.99 | 0.81 | 0.79 | 0.74 | 0.20 | 0.47 |
| MIRO | 0.3B | 18M | 0.75 | 0.98 | 0.79 | 0.71 | 0.85 | 0.58 | 0.58 |
| Ours | 1B | 1.2M | 0.67 | 0.98 | 0.82 | 0.47 | 0.85 | 0.36 | 0.52 |
DPGBench
On DPGBench, a more complex benchmark, our model reaches 81.2 overall, surpassing SDXL and PixArt-Σ and matching Janus. It trails FLUX-dev and SANA-0.6 by about 3 points but is the best on Relation (93.0).
| Model | Overall ↑ | Entity | Attribute | Relation | Other | Global |
|---|---|---|---|---|---|---|
| SD v1.5 | 63.2 | 74.2 | 75.4 | 73.5 | 67.8 | 74.6 |
| PixArt-α | 71.1 | 79.3 | 78.6 | 82.6 | 77.0 | 75.0 |
| SDXL | 74.7 | 82.4 | 80.9 | 86.8 | 80.4 | 83.3 |
| CAD | 77.6 | 85.3 | 84.7 | 91.5 | 74.8 | 84.5 |
| PixArt-Σ (512) | 79.5 | 87.1 | 86.5 | 84.0 | 86.1 | 87.5 |
| Janus | 79.7 | 87.4 | 87.7 | 85.5 | 86.4 | 82.3 |
| PixArt-Σ (1024) | 80.5 | 82.9 | 88.9 | 86.6 | 87.7 | 86.9 |
| FLUX-dev | 84.0 | 89.5 | 88.7 | 91.1 | 89.4 | 82.1 |
| SD3 Medium | 84.1 | 91.0 | 88.8 | 80.7 | 88.7 | 87.9 |
| SANA-0.6 | 84.3 | 90.0 | 88.6 | 90.1 | 91.9 | 82.6 |
| Ours | 81.2 | 88.4 | 86.4 | 93.0 | 76.0 | 82.1 |
6 · Generalization
Beyond ImageNet's objects
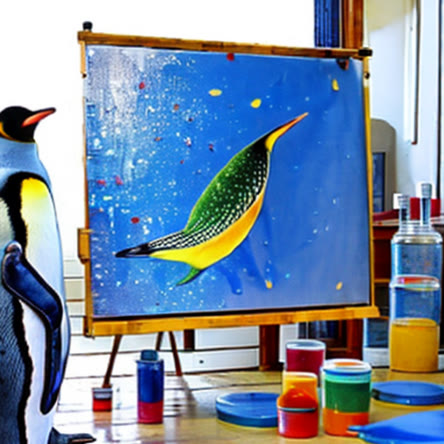
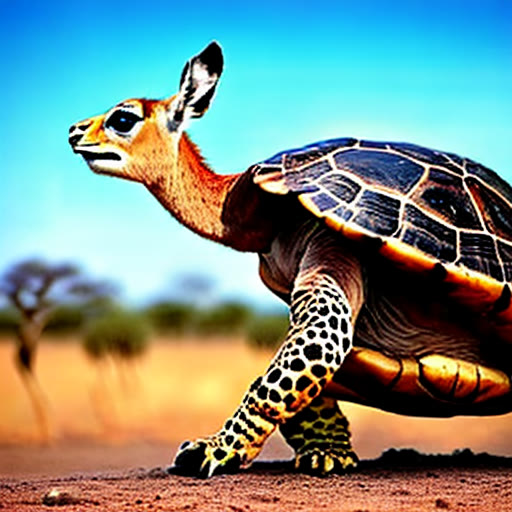
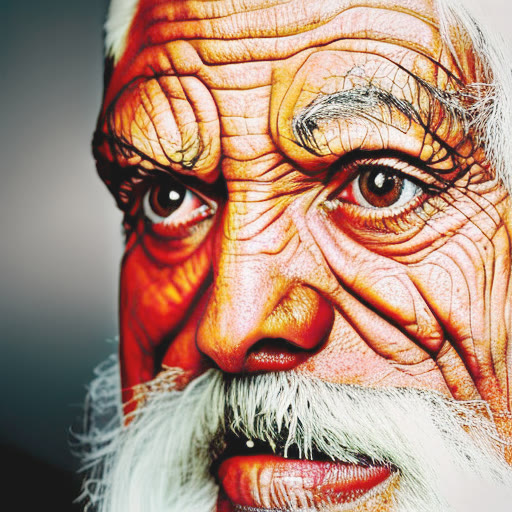
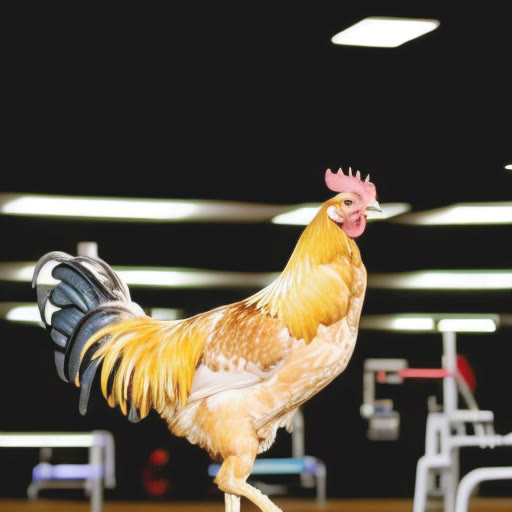
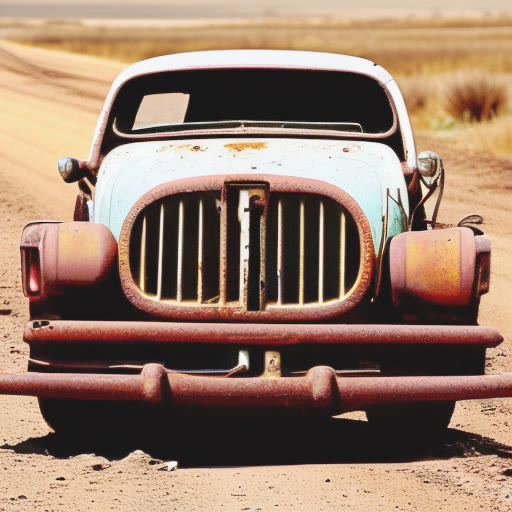
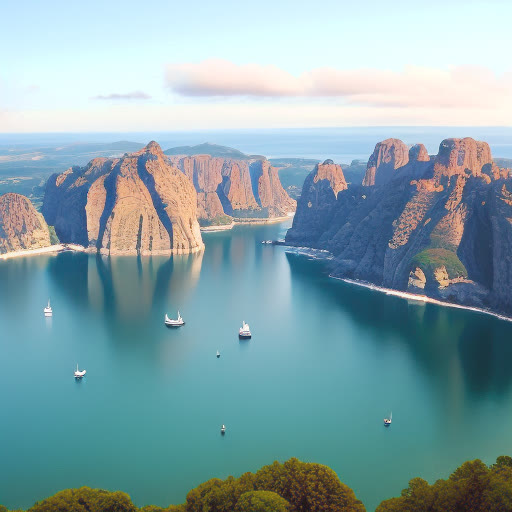
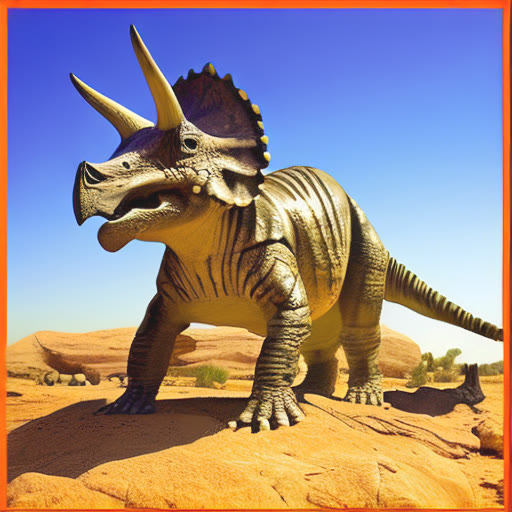
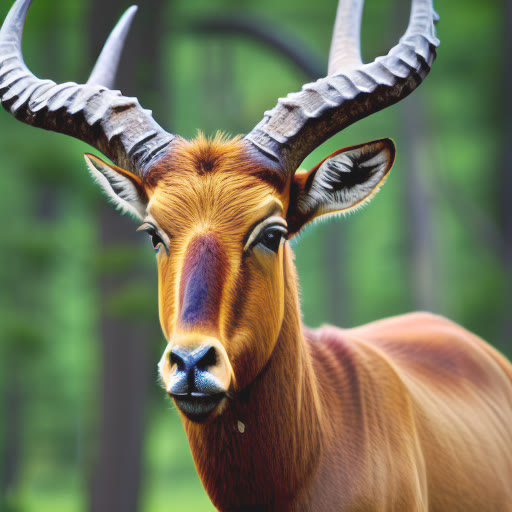
Despite ImageNet's object-centric bias, our models compose complex scenes and approximate concepts never seen during training, by combining patterns from training concepts. For example, the model creates a hybrid creature mixing a giraffe and a tortoise, leveraging the text understanding of the language model that encodes the prompt.
Samples
512² samples, trained only on ImageNet
BibTeX
@article{degeorge2025farimagenettexttoimagegeneration,
  title   = {How far can we go with ImageNet for Text-to-Image generation?},
  author  = {Degeorge, Lucas and Ghosh, Arijit and Dufour, Nicolas and
             Picard, David and Kalogeiton, Vicky},
  journal = {arXiv preprint arXiv:2502.21318},
  year    = {2025}
}
Acknowledgments
This work was granted access to the HPC resources of IDRIS under the allocation 2025-AD011015436 and 2025-AD011015594 made by GENCI, and by the SHARP ANR project ANR-23-PEIA-0008 funded in the context of the France 2030 program. The authors would like to thank Alexei A. Efros, Thibaut Loiseau, Yannis Siglidis, Yohann Perron, Louis Geist, Robin Courant and Sinisa Stekovic for their insightful comments, suggestions, and discussions.